

合格させる3V0-24.25ブレーン問題集で更新されたのは認定サンプル問題
オンライン3V0-24.25テストブレーン問題集とテストエンジン
質問 # 27
What is the function ofContourin a VMware vSphere Kubernetes Service (VKS) cluster?
- A. Managing the lifecycle and patching of VKS cluster nodes.
- B. Monitoring the health and performance of the underlying infrastructure.
- C. Providing an ingress controller to expose services to external users.
- D. Providing persistent storage for stateful applications.
正解:C
解説:
In VCF 9.0, ingress is described as part ofVKS cluster networking. The documentation's VKS Cluster Networking table lists"Cluster ingress"and identifies its role asrouting inbound pod traffic. It further clarifies that this function is delivered by athird-party ingress controller, and explicitly namesContouras an example ("you can use any third-party ingress controller, such as Contour").
That mapping is exactly what optionAdescribes: Contour is deployed to provideingresscapabilities so that inbound requests from outside the cluster can be routed to Kubernetes services and pods according to ingress rules. In other words, Contour is not a storage component (that would align to CSI/CNS/pvCSI), not a node lifecycle manager (that is handled by VKS/Cluster API/VM Service), and not an infrastructure health monitoring tool (that would be metrics/observability tooling). VCF 9.0 positions Contour specifically within theingresspart of the networking feature set, makingAthe correct answer.
質問 # 28
The vSphere Admin creates a vSphere Namespace harbor-project and grants the DevOps Engineer edit permissions. The DevOps Engineer deploys the Harbor service in thisnamespace with the command: kubectl apply -f harbor-svc.yml The Harbor service deploys successfully, but the database data harbor database 0 pods does not come into a Running state.
Click the two locations where the administrator should verify the Access Modes forthis pod's PerslstentVolumeClaim (PVC). (Choose two.)
正解:
解説: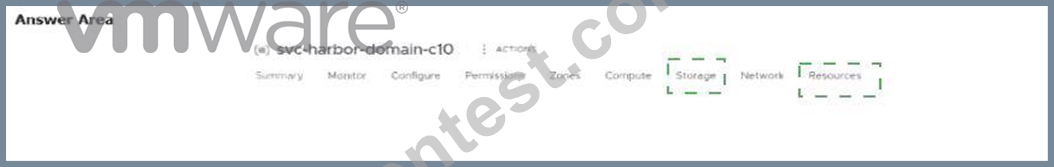
Explanation:
* Storage
* Resources
When a stateful pod (like Harbor's database) is stuck Pending/ContainerCreating or repeatedly failing to attach
/mount storage, one of the first checks is whether the PVC'sAccess Modesmatch what the workload and backing storage support (for example, ReadWriteOnce vs ReadWriteMany). In Kubernetes, the PVC and PV explicitly showAccess Modes(for example Access Modes: RWO) when you inspect them.
In the vSphere Namespace UI, theStoragetab is where namespace storage is managed and reviewed (including storage policy assignments that back storage classes/PVCs), making it the natural place to validate the storage configuration being consumed by the Harbor database PVC. VMware's VCF documentation directs administrators to navigate to a namespace and use theStoragetab for storage-related settings.
TheResourcestab is the Kubernetes-object oriented view for the namespace, where you can locate the PVC object associated with the failing pod and inspect its properties/YAML (including the requested storage class and access mode intent). Namespace permissions explicitly include the ability to view Kubernetes resources within the namespace, which aligns with checking PVC details there.
質問 # 29
A Cloud Administrator is designing a multi-tenant vSphere with Tanzu environment for two distinct business units: Finance and Engineering.
Requirements:
1. Finance requires strict egress filtering. All outbound traffic must originate from a predictable, static IP address range to pass through a legacy firewall.
2. Engineering requires high-volume ingress. They plan to deploy 50+ unique web services, each needing public access, but the available Floating IP Pool for the Load Balancer is limited to 10 IPs.
3. Isolation: Traffic between Finance and Engineering must be blocked by default.
Review the proposed design configuration:
# Namespace: finance-ns
Network: NSX (NAT Mode)
Egress: Configured with SNAT
# Namespace: engineering-ns
Network: NSX (NAT Mode)
Services: Developers instructed to use 'type: LoadBalancer' for all apps.
Which aspects of this design need correction or validation to meet the requirements? (Select all that apply.)
- A. The Isolation requirement is automatically met because NSX-backed Namespaces are deployed with distinct Tier-1 Gateways and a default "Deny All" Distributed Firewall policy between them is often required (or naturally isolated by T1 routing rules depending on T0 config). Self-correction: VKS Namespaces are isolated by default in terms of not sharing T1s, but traffic routing depends on T0.
However, the question asks about valid/invalid aspects. A DFW rule or Network Policy is the standard way to enforce "Blocked by default" between namespaces. - B. The Finance namespace should be configured in "Routed Mode" (No-NAT) to simplify the firewall rules.
- C. The Finance design is valid; enabling NSX NAT Mode with SNAT ensures that all pod traffic leaves the namespace using a deterministic "Egress IP" assigned to the T1 Gateway, which satisfies the firewall requirement.
- D. The Engineering design is flawed; using type: LoadBalancer for 50+ services will exhaust the 10-IP pool. An Ingress Controller (L7) architecture must be mandated to multiplex these services behind a single VIP.
- E. The Engineering namespace needs a separate Supervisor Cluster to support that many services.
正解:C、D
質問 # 30
What is the standard procedure for upgrading the vSphere Supervisor Cluster to a newer version?
- A. The upgrade requires a complete re-installation of the Supervisor Cluster; workload data must be backed up and restored manually.
- B. The upgrade is initiated from the vSphere Client by selecting the Supervisor Cluster and choosing a target version, which triggers a rolling update of the Control Plane VMs and the Spherelet agents on the ESXi hosts.
- C. The administrator must download an ISO image, mount it to each Control Plane VM, and run an upgrade script manually.
- D. The upgrade is performed exclusively through the NSX Manager interface, as it controls the Supervisor networking.
正解:B
質問 # 31
A Platform Engineer needs to configure a vSphere Namespace to allow a specific Active Directory group, [email protected], to have full administrative access to the Kubernetes namespace, including the ability to create and delete TKG clusters. The solution must follow the principle of least privilege within vSphere.
Which configuration steps in the vSphere Client will achieve this? (Select all that apply.)
- A. In the Namespace permissions, add [email protected] with the CanEdit role.
- B. In the Namespace permissions, add [email protected] with the Owner role.
- C. Assign the Administrator role to [email protected] at the vCenter Server Global Permissions level.
- D. Assign the NSX Administrator role to [email protected] in NSX Manager.
- E. Ensure the Identity Source corp.local is configured in vCenter Single Sign-On.
正解:B、E
質問 # 32
Which type of storage is used by VMware vSphere Kubernetes Service (VKS) pods to store non-persistent data?
- A. Object storage
- B. Ephemeral storage
- C. vSphere local storage
- D. Container image storage
正解:B
解説:
In Kubernetes terms,non-persistentpod data (for example, transient logs and scratch space) is handled byephemeral storage, meaning the data exists only for the lifetime of the pod/workload and is not meant to survive beyond it. In the VCF Workload Management documentation, this concept is described directly: a pod requiresephemeral storageto store transient Kubernetes objects such as "logs" and "emptyDir volumes," and this ephemeral (transient) storage "lasts as long as the pod continues to exist," disappearing when the pod reaches end of life.
While VKS clusters can also consumepersistent storagethrough storage classes and CSI integration for stateful needs, that is specifically for data that must be retained (persistent volumes/claims). The question asks specifically aboutnon-persistentpod data, which aligns with the documented ephemeral/transient storage behavior for pod runtime needs. Therefore, the correct choice isEphemeral storage.
質問 # 33
Which object type does the Kubernetes RBAC API declare?
- A. ValidatingAdmissionPolicy and ResourceQuotas
- B. Container and Deployment
- C. ClusterRole and ClusterRoleBinding
- D. ClusterObject and ClusterNode
正解:C
解説:
Kubernetes Role-Based Access Control (RBAC) is implemented through theRBAC API group(rbac.authorization.k8s.io) and defines the core authorization primitives used to grant permissions to users, groups, and service accounts. The cluster-scoped objects declared by the RBAC API areClusterRoleandClusterRoleBinding. AClusterRoledefines a set of permissions (verbs such as get/list/watch/create/update/delete) over resources at thecluster scope(including cluster-wide resources and optionally namespaced resources across namespaces). AClusterRoleBindingthenbindsthat ClusterRole to a subject (user/group/serviceaccount), making those permissions effective cluster-wide.
This differs from namespace-scoped RBAC objects (RoleandRoleBinding) which apply only within a single namespace. The other options are incorrect becauseClusterObject/ClusterNodeare not RBAC API objects, ValidatingAdmissionPolicybelongs to the admission control API surface (policy enforcement), ResourceQuotais a namespace resource governance object, andContainer/Deploymentare workload/runtime concepts defined in the core/apps APIs rather than authorization primitives.
質問 # 34
A DevOps team is deploying a legacy application that requires a specific Private Registry (registry.internal.corp) to pull its container images. This registry requires authentication.
To avoid modifying every individual Pod manifest to include imagePullSecrets, the Platform Engineer wants to configure a default deployment model for the namespace legacy-apps.
Which configuration applies the pull secret automatically to all Pods launched by the standard default ServiceAccount in that namespace?
- A. Edit the TanzuKubernetesCluster spec to include the registry credential in the settings.network.trust section.
- B. Create a Secret named default-token in the namespace; Kubernetes uses this automatically for all registries.
- C. Create a ConfigMap named standard-registry and mount it to every pod using a MutatingAdmissionWebhook.
- D. Patch the default ServiceAccount in the legacy-apps namespace to add the secret name to the imagePullSecrets list.
正解:D
質問 # 35
A VKS Administrator is troubleshooting a failed package installation. A developer attempted to install the fluent-bit package, but the PackageInstall resource status reports a reconciliation failure.
The administrator inspects the PackageRepository status:
$ kubectl get packagerepository -n tkg-system
NAME AGE DESCRIPTION
private-repo 10m Reconcile failed: Error: Imgpkg: Fetching image:
Head "https://private-reg.corp.local/repo/packages:v1":
x509: certificate signed by unknown authority
The environment uses a private Harbor registry (private-reg.corp.local) signed by an internal Corporate Root CA.
What is the correct procedure to resolve this trust issue and allow the cluster to pull packages? (Choose
2.)
- A. Disable TLS verification on the kapp-controller deployment by editing the deployment spec.
- B. Obtain the Corporate Root CA certificate in PEM format.
- C. Reconfigure the TKG cluster by updating its TanzuKubernetesCluster spec to include the trust.additionalTrustedCAs field with the Corporate Root CA name/data.
- D. Create a Kubernetes Secret of type Opaque (or generic) in the tkg-system namespace containing the CA certificate (key ca.crt), then reference this secret in the spec.fetch.imgpkgBundle.secretRef (or appropriate CA trust field if supported by the specific API version) of the PackageRepository YAML. Self- Correction/Refinement: The standard TKG way to trust a registry CA for the whole cluster (including containerd and kapp) is typically at cluster creation via the TkgServiceConfiguration or ClusterClass, OR by patching the cluster. However, for kapp-controller specific trust, referencing a CA secret or ensuring the node trusts it is key.
- E. Manually copy the CA certificate to /etc/ssl/certs on every worker node and reboot them.
正解:B、C
質問 # 36
An administrator is upgrading an existing VMware vSphere Kubernetes Service (VKS) cluster and receives the following errors:
* kubectl get nodes fails with memcache.go and "server is currently unable to handle the request"
* couldn't get resource list for stats.antrea.tanzu.vmware.com/v1alpha1
* yaml: mapping values are not allowed in this context
The administrator successfully updated the Supervisor, but an attempt to update the VKS cluster failed. Based on the scenario, what is the cause of the problem?
- A. The administrator is in the wrong cluster context.
- B. The administrator does not have the appropriate permissions to upgrade the cluster.
- C. The Kubernetes version being upgraded is no longer supported.
- D. There was an error pulling the update image from the catalog.
正解:A
解説:
The errors described-specifically the memcache.go failure, the inability to fetch resource lists for Antrea, and the YAML context error-are classic symptoms of aConfiguration Context mismatch. In VCF 9.0, there are two distinct layers of API interaction: theSupervisor Cluster API(used for management tasks like creating clusters) and theGuest Cluster API(used for deploying workloads within the VKS).
When an administrator upgrades a Supervisor, the API endpoint or the available API groups may change. If the administrator attempts to run kubectl commands against a VKS cluster while their kubeconfig context is still pointing to the Supervisor (or vice versa), the client will encounter "mapping values" errors and "unable to handle request" errors because it is sending requests to an endpoint that does not recognize those specific resource definitions (like Antrea stats in the wrong context). To resolve this, the administrator must ensure they have switched to the correct context using kubectl config use-context <cluster-name> after the Supervisor update to ensure the local client is communicating with the correct API server and version of the Kubernetes binaries.
質問 # 37
A cloud platform team is deploying multiple Supervisors in a VMware Cloud Foundation (VCF) environment to support a multi-tenant VKS architecture. Each Supervisor will host a distinct set of namespaces mapped to different organizational tenants such as Finance, Public Services, and R&D, where each tenant consumes resources from dedicated workload domains.
What is the purpose of the vcf context create command?
- A. Creates a connection to VCF Operations for the current session.
- B. Creates a named set of access parameters for a VKS cluster.
- C. Provides authentication to the Supervisor cluster.
- D. Creates a new storage profile for a cluster.
正解:B
解説:
VCF 9.0 defines aVCF CLI contextas aconfiguration setfor a specific endpoint (for example, a Kubernetes cluster, vSphere Supervisor, or VCF Automation) and explains that a context stores the key connection parameters such asendpoint,context type,path to kubeconfig, andcredentials. This aligns directly with optionC, because vcf context create is used to create anamedcontext that encapsulates the access parameters needed to work with a specific Supervisor or VKS cluster and to switch between multiple environments without rewriting configuration each time.
The documentation further shows vcf context create being used to connect either to aSupervisor endpointor to aworkload (VKS) cluster(by providing workload cluster name/namespace or by using a generated kubeconfig), which is exactly the multi-tenant operational pattern in the question. While authentication is part of what happens during context creation (for example, creating a configuration that includes a JWT for Kubernetes API access), the command's purpose is broader: it creates the reusablecontextobject that defineswhereandhowthe CLI connects.
質問 # 38
An administrator is configuring the Supervisor Service in vCenter.
Click the option an administrator uses to begin creating a vSphere Supervisor Zone.
正解:
解説: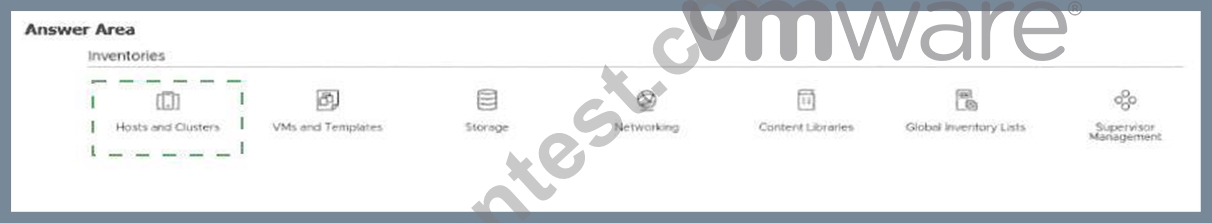
Explanation:
Hosts and Clusters
To create avSphere Zone(used as a Supervisor Management Zone and/or Workload Zone), the administrator must start from the vSphere Client inventory wherevCenterand its clusters are managed. That's why the correct starting point in the "Inventories" toolbar isHosts and Clusters-it is the entry point used to select the vCenter object and the target clusters.
VCF 9.0 documents the zone-creation workflow as:navigate to vCenter, thenSelect Configure, thenselect vSphere Zones, and finally clickAdd New vSphere Zone. After naming the zone, youselect a vSphere cluster to add to the zoneand finish the wizard.
This sequence matches the intent of the hotspot: you must first open the inventory view that exposes vCenter and clusters (Hosts and Clusters), then perform the configuration steps under vCenter to define vSphere Zones. Once created, these zones can later be selected during Supervisor deployment (for multi-zone placement) or assigned to namespaces for workload placement.
質問 # 39
A Platform Engineer is troubleshooting a failed installation of the external-dns Supervisor Service.
The service status in the vSphere Client is "Error".
The engineer retrieves the logs from the service's pod and sees the following:
time="2023-11-22T10:00:00Z" level=error msg="rfc2136: failed to send TSIG authenticated message:
dns: failed to pack message: dns: bad secret"
time="2023-11-22T10:00:05Z" level=error msg="source: failed to list vSphere resources: Unauthorized" The configuration YAML provided during installation included the following snippet for the DNS provider:
spec:
provider: rfc2136
rfc2136:
host: 192.168.10.5
zone: corp.local
tsigSecretName: external-dns-tsig-secret
What is the most likely cause of the failure? (Choose 2.)
- A. The rfc2136 provider is not supported by vSphere with Tanzu.
- B. The Supervisor Cluster does not have a route to the DNS server 192.168.10.5.
- C. The storage policy for the service is full.
- D. The Kubernetes Secret external-dns-tsig-secret referenced in the config does not exist in the namespace where the service is being deployed, or it contains an incorrect TSIG key.
- E. The external-dns service account does not have the necessary RBAC permissions on the Supervisor to watch/list Service and Ingress resources.
正解:D、E
質問 # 40
In a vSphere with Tanzu environment, what is the primary source of truth for identity and authentication for the Supervisor Cluster?
- A. The Supervisor maintains its own independent local user database stored in etcd.
- B. Authentication is handled exclusively by the NSX Manager identity store.
- C. vCenter Single Sign-On (SSO) is the central identity provider; the Supervisor federates with vCenter SSO to authenticate users.
- D. The Supervisor must be connected directly to an external LDAP server, bypassing vCenter Server.
正解:C
質問 # 41
A customer is required to enhance the security for a set of VMware vSphere Kubernetes Service (VKS) clusters that host services interacting with sensitive customer data. The solution must encrypt the transport and communications between services.
The VKS Admin recommends enabling Istio Service Mesh to satisfy the requirement. What type of encryption does Istio Service Mesh provide?
- A. SSH or TLS
- B. IPsec with IKEv2
- C. AES 256
- D. mTLS
正解:D
解説:
Istio is available in VCF 9.0 as an optional package that can be installed for VKS clusters. The VCF 9.0 documentation explicitly lists "Istio" among the optional packages that "can be optionally installed" for the vSphere Kubernetes Service (VKS). In Kubernetes platforms, Istio is a service mesh that secures and manages service-to-service (east-west) traffic by establishing authenticated and encrypted connections between workloads. The encryption mechanism it provides for inter-service communication ismutual TLS (mTLS), which means both ends (client and server workloads) authenticate each other and negotiate encrypted transport for every service call-meeting the requirement to "encrypt the transport and communications between services." This is distinct from host-level mechanisms like IPsec/IKEv2 (network-layer) or "AES-
256" (an algorithm, not the service-to-service transport model). Enabling Istio Service Mesh is therefore aligned to deliver encrypted, identity-aware service communications across the cluster at the application service layer.
質問 # 42
......
リアルVMware 3V0-24.25試験問題集には正解173問題と解答があります:https://www.jpntest.com/shiken/3V0-24.25-mondaishu
VMware 3V0-24.25認定のリアル2026年最新の模擬試験:https://drive.google.com/open?id=1O6aONuWcYDs9rx7vu1lu1gngBUQm2Od1