 445 お客様のコメント

さまざまな記憶方法
毎日新しい知識を学んでいるだけでなく、常に忘れられていた知識も私たちは記憶と鍛造の過程にあったと言うことができます。 これには優れたメモリアプローチが必要です、そしてApache-Hadoop-Developer研究の脳ダンプはそれを上手く行います。Apache-Hadoop-Developer準備ガイドは、テキスト、画像、グラフィックメモリ方式などの多様化を採用し、情報を学ぶためにマークアップを区別する必要があります。 全体的なレイアウト、目標とされた長期記憶の形成へのより良い手がかり、そして実践のサイクルを通して、知識をより深く私の頭の中に印刷させてください。Apache-Hadoop-Developer試験問題は非常に科学的かつ妥当であり、あなたは簡単にすべてを覚えることができます。
私たちのApache-Hadoop-Developer研究の問題集は、この点でユーザの要求を満たすのに非常に役立ちます。Apache-Hadoop-Developer準備ガイドは高品質です。 それでテストの準備をするためのすべての効果的な中心的な習慣があります。 私たちの職業的能力により、Apache-Hadoop-Developer試験問題を編集するのに必要なテストポイントに同意することができます。 それはあなたの難しさを解決するための試験の中心を指しています。 だから高品質の材料はあなたが効果的にあなたの試験に合格し、目標を達成するために簡単に感じるようにすることができます。
便利なPDFダウンロードモード
ユーザーのオフラインでの読解を容易にするために、Apache-Hadoop-Developer学習問題集は、特にユーザー向けのPDFモードを開発するために、破片の時間を学習に使用することができます。 このモードでは、ユーザーはダウンロードして印刷すること、紙にメモを取ることが簡単であること、および自分の記憶の弱いリンクを学ぶために、教材内のApache-Hadoop-Developer準備ガイドを知ることができます。 我々のApache-Hadoop-Developer試験問題とユーザの効率を非常に改善します。 あるいは、いわゆる「いい」を忘れてしまうかもしれませんが、今ではオンラインで読むのに便利なあらゆる種類のデジタル機器ですが、私たちの多くは、彼らの記憶パターンを深めるために書面で使われています。 私たちのApache-Hadoop-Developer準備ガイドは、この点でユーザーの需要を満たすのに非常に良いものです。ユーザーが良い環境で読み書きできるようにすることで、学んだことを継続的に統合することができます。
強力なユーザー共有プラットフォーム
もちろん、個人的な学習効果は特に目立ちません。なぜなら、この問題を解決するために、テストの難点、良いアップデートを同時に得られないという最新の試験の傾向を掴むのは難しいからです。 圧倒的多数のユーザーのためのApache-Hadoop-Developer研究問題集は、ユーザーが共有するための強力なプラットフォームを提供します。 ここでは、Apache-Hadoop-Developer試験問題のすべてのユーザが自分のID番号を通してプラットフォームと他のユーザにログオンして共有し交換することができ、プラットフォーム上でさらに仲良くなるために多くの人々と努力することができます。 他の、学習や生活の中で彼らの困難を解決するためにお互い。Apache-Hadoop-Developer準備ガイドは、学習環境だけでなく、家庭のような学習環境を作成することもできます。
Hortonworks Apache-Hadoop-Developer 試験シラバストピック:
| セクション | 目標 |
|---|---|
| トピック 1: Hadoop エコシステムの基礎 | - YARN とリソース管理
|
| トピック 2: Apache Hive | - HiveQL クエリ言語
|
| トピック 3: データ処理と統合 | - Hadoop のデータフォーマット
|
| トピック 4: Apache Pig | - Pig の実行モデル
|
Hortonworks Hadoop 2.0 Certification exam for Pig and Hive Developer 認定 Apache-Hadoop-Developer 試験問題:
In a MapReduce job, the reducer receives all values associated with same key. Which statement best describes the ordering of these values?
- A. The values are arbitrarily ordered, and the ordering may vary from run to run of the same MapReduce job.
- B. The values are in sorted order.
- C. The values are arbitrary ordered, but multiple runs of the same MapReduce job will always have the same ordering.
- D. Since the values come from mapper outputs, the reducers will receive contiguous sections of sorted values.
正解:A 🗳️
解説: (JPNTest メンバーにのみ表示されます)
In a large MapReduce job with m mappers and n reducers, how many distinct copy
operations will there be in the sort/shuffle phase?
- A. mXn (i.e., m multiplied by n)
- B. n
- C. mn (i.e., m to the power of n)
- D. m+n (i.e., m plus n)
- E. m
正解:A 🗳️
解説: (JPNTest メンバーにのみ表示されます)
When can a reduce class also serve as a combiner without affecting the output of a MapReduce program?
- A. When the types of the reduce operation's input key and input value match the types of the reducer's output key and output value and when the reduce operation is both communicative and associative.
- B. Always. The point of a combiner is to serve as a mini-reducer directly after the map phase to increase performance.
- C. When the signature of the reduce method matches the signature of the combine method.
- D. Always. Code can be reused in Java since it is a polymorphic object-oriented programming language.
- E. Never. Combiners and reducers must be implemented separately because they serve different purposes.
正解:A 🗳️
解説: (JPNTest メンバーにのみ表示されます)
You want to run Hadoop jobs on your development workstation for testing before you submit them to your production cluster. Which mode of operation in Hadoop allows you to most closely simulate a production cluster while using a single machine?
- A. Run all the nodes in your production cluster as virtual machines on your development workstation.
- B. Run the DataNode, TaskTracker, NameNode and JobTracker daemons on a single machine.
- C. Run the hadoop command with the -jt local and the -fs file:///options.
- D. Run simldooop, the Apache open-source software for simulating Hadoop clusters.
正解:B 🗳️
Given the following Hive commands: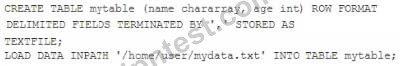
Which one of the following statements Is true?
- A. The file mydata.txt is copied into Hive's underlying relational database 0.
- B. The file mydata.txt is copied to a subfolder of /apps/hive/warehouse
- C. The file mydata.txt is moved to a subfolder of /apps/hive/warehouse
- D. The file mydata.txt does not move from Its current location in HDFS
正解:B 🗳️


 0
 0
 0
 0
