

DP-600日本語練習Microsoft高合格率回答あなたを試験は高確率で合格させます![2025]
最高の方法からパスMicrosoft CertifiedのDP-600日本語試験合格させます
質問 # 25
Warehouse1 という名前の倉庫を含むファブリック テナントがあります。 Warehouse1 には、schemaA、schemaB という名前の 3 つのスキーマが含まれています。 User1 という名前のユーザーが schemaA のテーブルのみを切り詰めることができるようにする必要があります。
T-SQL ステートメントはどのように完成させるべきでしょうか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。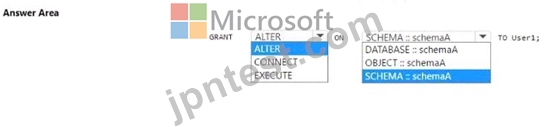
正解:
解説: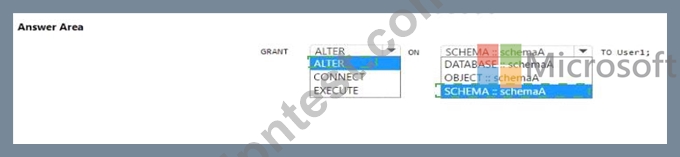
Explanation:
* GRANT ALTER ON SCHEMA::schemaA TO User1;
The ALTER permission allows a user to modify the schema of an object, and granting ALTER on a schema will allow the user to perform operations like TRUNCATE TABLE on any object within that schema. It is the correct permission to grant to User1 for truncating tables in schemaA.
References =
* GRANT Schema Permissions
* Permissions That Can Be Granted on a Schema
質問 # 26
OneLake に新しいセマンティック モデルを含む Fabric テナントがあります。
Fabric ノートブックを使用して、データを Spark DataFrame に読み取ります。
データを評価して、すべての文字列列と数値列の最小値、最大値、平均値、標準偏差の値を計算する必要があります。
解決策: 次の PySpark 式を使用します。
df.show()
これは目標を達成していますか?
- A. いいえ
- B. はい
正解:A
解説:
The df.show() method also does not meet the goal. It is used to show the contents of the DataFrame, not to compute statistical functions. Reference = The usage of the show() function is documented in the PySpark API documentation.
質問 # 27
Sales.Products という名前のテーブルを含む Fabric ウェアハウスがあります。 Sales.Products には次の列が含まれます。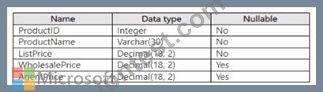
次の列を返す T-SQL クエリを作成する必要があります。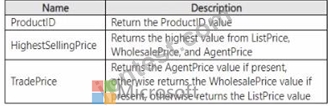
コードをどのように完成させるべきでしょうか?回答するには、回答領域で適切なオプションを選択してください。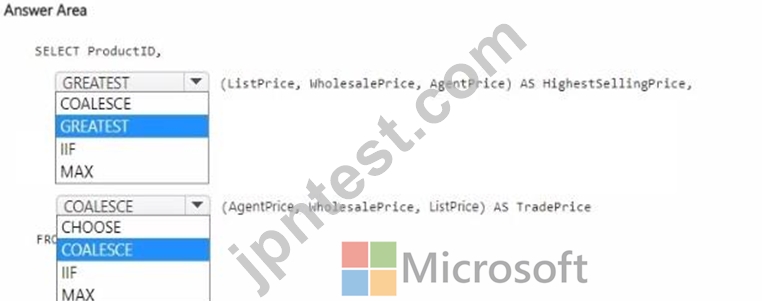
正解:
解説: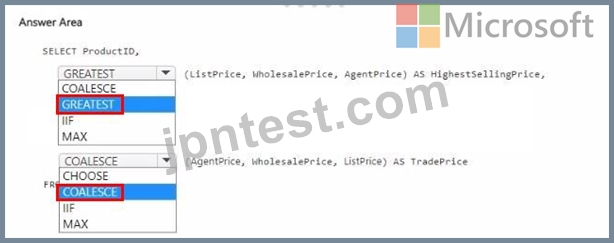
質問 # 28
注: この質問は、同じシナリオを提示する一連の質問の一部です。一連の質問にはそれぞれ、定められた目標を満たす可能性のある独自の解決策が含まれています。質問セットによっては、正しい解決策が複数ある場合もあれば、正しい解決策がない場合もあります。
このセクションで質問に答えた後は、そのセクションに戻ることはできません。そのため、これらの質問はレビュー画面に表示されません。
Model1 という名前のセマンティック モデルを含む Fabric テナントがあります。
次のクエリは Model1 に対して実行が遅いことがわかります。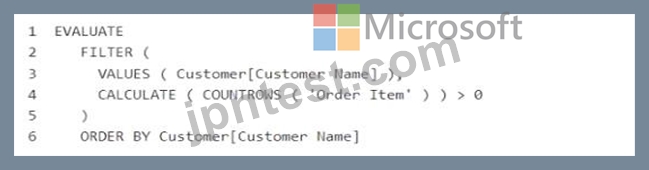
クエリの実行時間を短縮する必要があります。
解決策: 次のコードを使用して 4 行目を置き換えます。
これは目標を満たしていますか?
- A. はい
- B. いいえ
正解:A
質問 # 29
次の図に示すソース データ モデルがあります。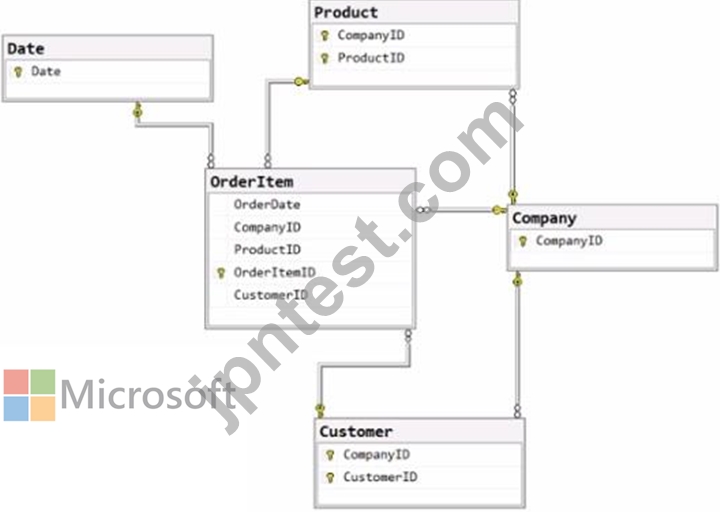
テーブルの主キーは、各キーに含まれる列の横にあるキー記号で示されます。
注文品目を日付、製品、顧客ごとに分析できるようにする次元データ モデルを作成する必要があります。
ソリューションには何を含めるべきでしょうか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。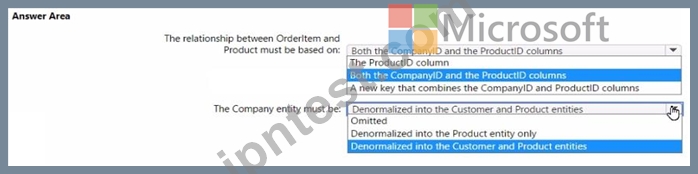
正解:
解説: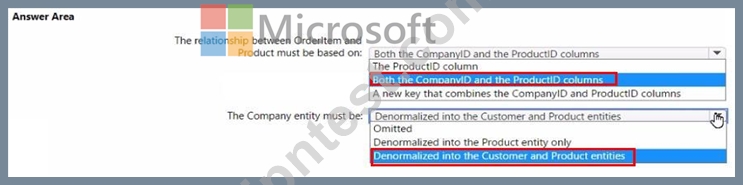
Reference:
Dimensional modeling
Star schema design
質問 # 30
Report 1 という名前の Microsoft Power Bl レポートを含む Fabric テナントがあります。Report1 には Python ビジュアルが含まれています。ビジュアルによって表示されるデータは自動的にグループ化され、重複した行は表示されません。
ビジュアルにすべての行を表示する必要があります。あなたは何をするべきか?
- A. Python コード内の列をインデックスで参照します。
- B. 各行に一意のフィールドを追加します。
- C. すべての列の Summarize By プロパティを変更します。
- D. すべての列の [列の並べ替え] プロパティを変更します。
正解:A
解説:
To ensure all rows appear in the Python visual within a Power BI report, option C, adding a unique field to each row, is the correct solution. This will prevent automatic grouping by unique values and allow for all instances of data to be represented in the visual. Reference = For more on Power BI Python visuals and how they handle data, please refer to the Power BI documentation.
質問 # 31
DW1 という名前のデータ ウェアハウスを含む Fabric テナントがあります。DW1 には、DimCustomer という名前のテーブルが含まれています。DimCustomer には、次の表に示すフィールドが含まれています。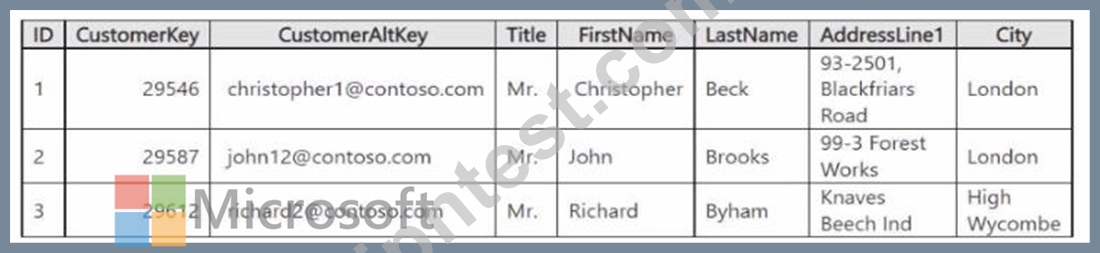
DimCustomer で重複する電子メール アドレスを識別する必要があります。ソリューションは最大 1,000 件のレコードを返す必要があります。
どの 4 つの T-SQL ステートメントを順番に実行する必要がありますか? 回答するには、ステートメントのリストから適切なステートメントを回答領域に移動し、正しい順序で並べます。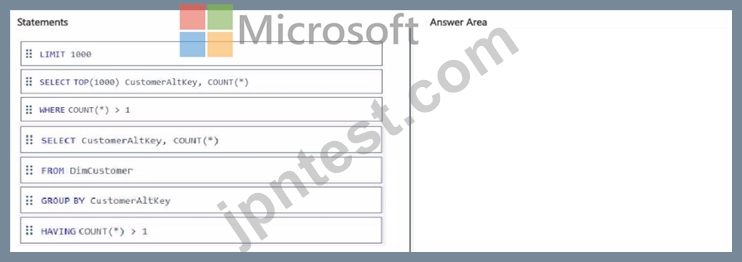
正解:
解説: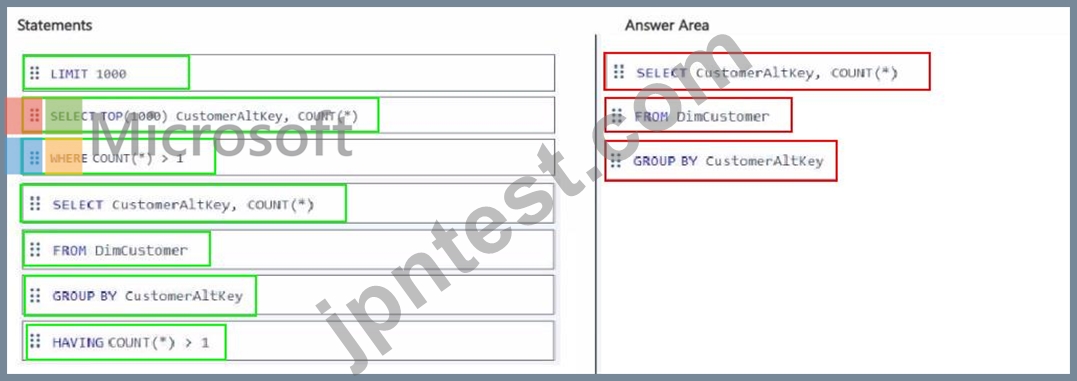
質問 # 32
倉庫を含む Fabric テナントがあります。
顧客ディメンションを含むスター スキーマ モデルを設計しています。顧客ディメンション テーブルは、タイプ 2 のゆっくりと変化するディメンション (SCD) になります。
テーブルに追加する列を推奨する必要があります。列はソース内にすでに存在していてはなりません。
どの 3 種類のカラムをお勧めしますか?それぞれの正解は、解決策の一部を示しています。
注: 各正解は 1 ポイントの価値があります。
- A. 有効な開始日時
- B. 有効な終了日時
- C. 代理キー
- D. 外部キー
- E. 自然キー
正解:A、B、C
解説:
For a Type 2 slowly changing dimension (SCD), you typically need to add the following types of columns that do not exist in the source system:
* An effective start date and time (E): This column records the date and time from which the data in the row is effective.
* An effective end date and time (A): This column indicates until when the data in the row was effective.
It allows you to keep historical records for changes over time.
* A surrogate key (C): A surrogate key is a unique identifier for each row in a table, which is necessary for Type 2 SCDs to differentiate between historical and current records.
References: Best practices for designing slowly changing dimensions in data warehousing solutions, which include Type 2 SCDs, are commonly discussed in data warehousing and business intelligence literature and would be part of the modeling guidance in a Fabric tenant's documentation.
質問 # 33
Dataflow1 という名前のデータ フローを含む Workspace1 という名前の Fabric ワークスペースがあります。 Dataflow1 には、次の図に示すデータを返すクエリが含まれています。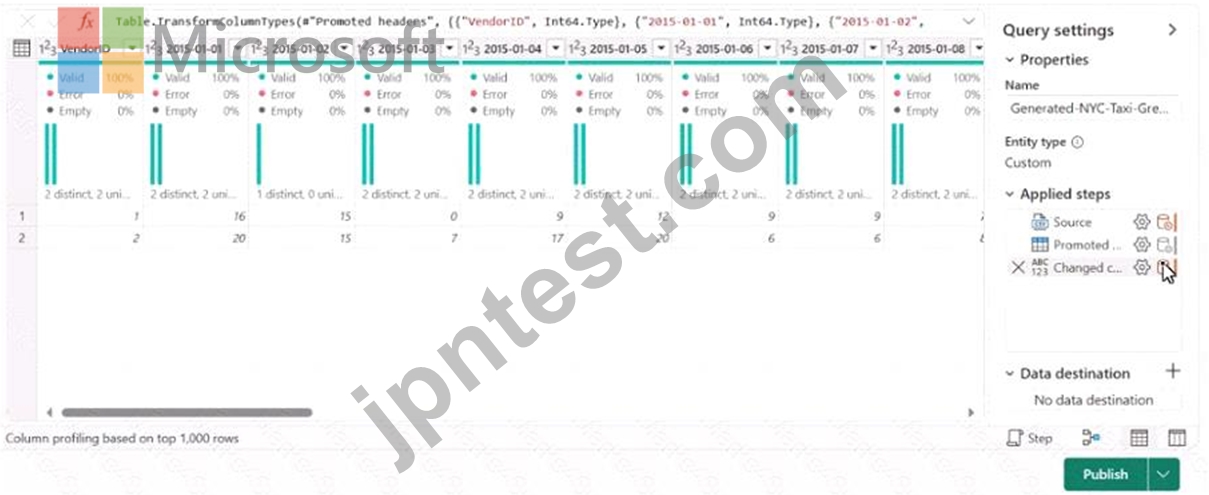
日付列を属性と値のペアに変換し、列が行になる必要があります。
VendorID 列を選択します。
VendorID 列のコンテキスト メニューからどの変換を選択する必要がありますか?
- A. グループ化
- B. 他の列のピボットを解除します
- C. 列を分割します
- D. 他の列を削除します
- E. 列のアンピボット
正解:E
解説:
The transformation you should select from the context menu of the VendorID column to transform the date columns into attribute-value pairs, where columns become rows, is Unpivot columns (B). This transformation will turn the selected columns into rows with two new columns, one for the attribute (the original column names) and one for the value (the data from the cells). References = Techniques for unpivoting columns are covered in the Power Query documentation, which explains how to use the transformation in data modeling.
質問 # 34
Workspace1 という名前の Fabric ワークスペースと、storage"! という名前の Azure Data Lake Storage Gen2 アカウントがあります。Workspace1 には、Lakehouse1 という名前のレイクハウスが含まれています。
ストレージへのショートカットを作成する必要があります。レイクハウス1にて。
どの接続とエンドポイントを指定する必要がありますか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。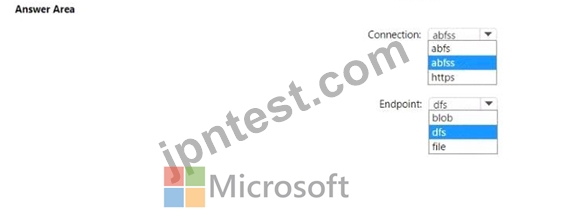
正解:
解説: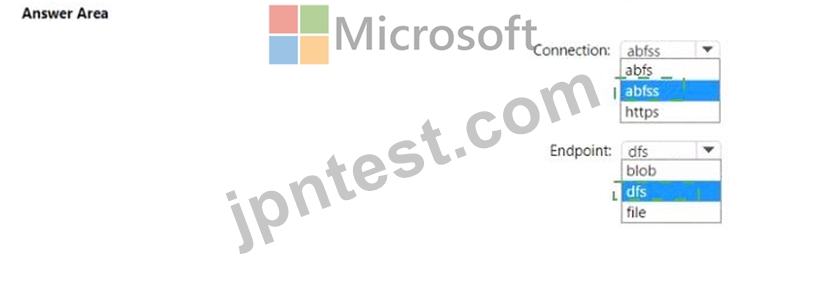
Explanation: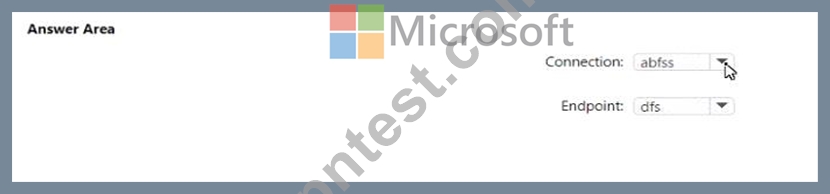
When creating a shortcut to an Azure Data Lake Storage Gen2 account in a lakehouse, you should use the abfss (Azure Blob File System Secure) connection string and the dfs (Data Lake File System) endpoint. The abfss is used for secure access to Azure Data Lake Storage, and the dfs endpoint indicates that the Data Lake Storage Gen2 capabilities are to be used.
質問 # 35
データ ストアに日付ディメンションを実装する必要があります。ソリューションは技術要件を満たしている必要があります。
目標を達成するための 2 つの方法は何ですか?それぞれの正解は完全な解決策を示します。
注: 正しく選択するたびに 1 ポイントの価値があります。
- A. パイプラインのストアド プロシージャ アクティビティを使用して、日付ディメンション テーブルにデータを入力します。
- B. パイプラインのコピー アクティビティを使用して、日付ディメンション テーブルにデータを入力します。
- C. データフローを使用して日付ディメンション テーブルにデータを入力します。
- D. T-SQL を使用して日付ディメンション ビューにデータを設定します。
正解:A、C
解説:
Both a dataflow (A) and a Stored procedure activity in a pipeline (B) are capable of creating and populating a date dimension table. A dataflow can perform the transformation needed to create the date dimension, and it aligns with the preference for using low-code tools for data ingestion when possible. A Stored procedure could be written to generate the necessary date dimension data and executed within a pipeline, which also adheres to the technical requirements for the PoC.
質問 # 36
Stage という名前のテーブルを含むデータ ウェアハウスがあります。お客様。 Stage-Customers には、顧客関係管理 (CRM) システムからのすべての顧客レコードの更新が含まれています。顧客ごとに複数の更新が存在する可能性があります。各顧客 ID の顧客 ID、名前、郵便番号、および最新行の最終更新時刻を返す T-SQL クエリを作成する必要があります。
コードをどのように完成させるべきでしょうか?回答するには、回答エリアで適切な選択肢を選択してください。 注 正しい選択肢はそれぞれ 1 ポイントの価値があります。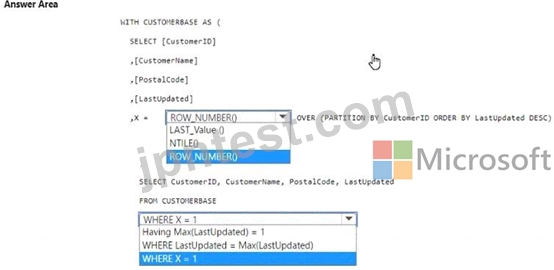
正解:
解説: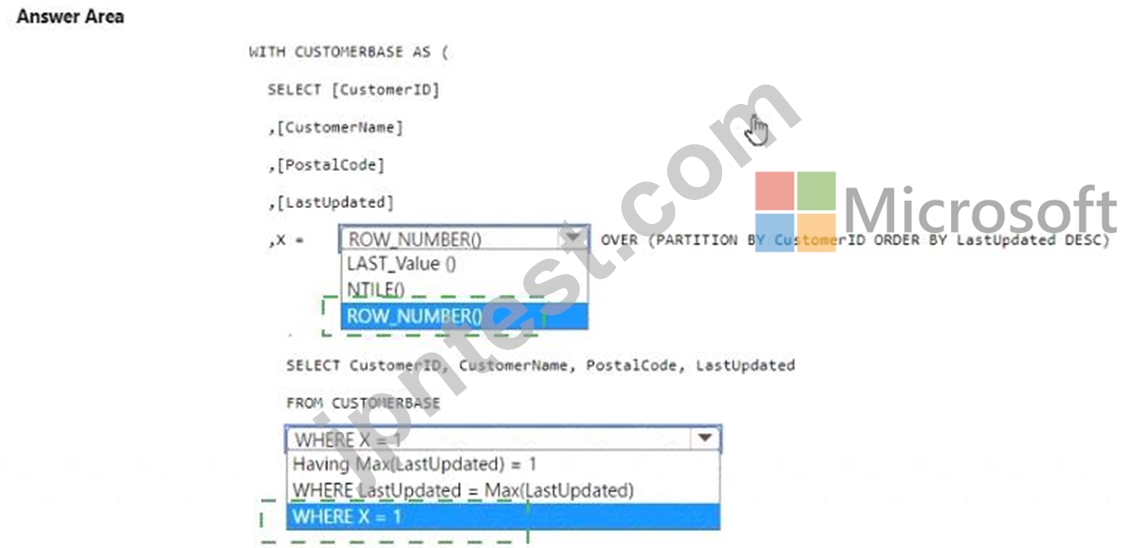
Explanation: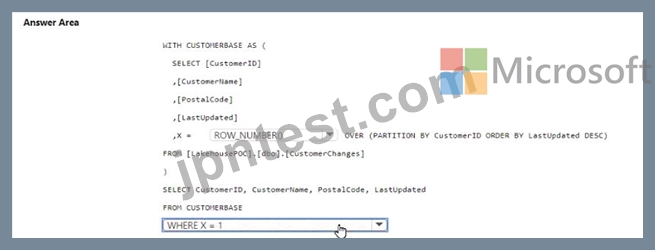
* In the ROW_NUMBER() function, choose OVER (PARTITION BY CustomerID ORDER BY LastUpdated DESC).
* In the WHERE clause, choose WHERE X = 1.
To select the most recent row for each customer ID, you use the ROW_NUMBER() window function partitioned by CustomerID and ordered by LastUpdated in descending order. This will assign a row number of 1 to the most recent update for each customer. By selecting rows where the row number (X) is 1, you get the latest update per customer.
References =
* Use the OVER clause to aggregate data per partition
* Use window functions
質問 # 37
Warehouse1 という名前の倉庫を含むファブリック テナントがあります。 Warehouse1 には、10 億行を含む FactSales という名前のファクト テーブルが含まれています。次の T-SQL ステートメントを実行します。
Dbo.FactSales のクローンとしてテーブル test.FactSales を作成します。
次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。 注: 正しく選択するたびに 1 ポイントの価値があります。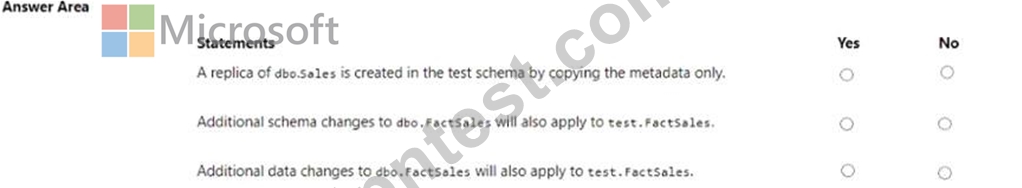
正解:
解説: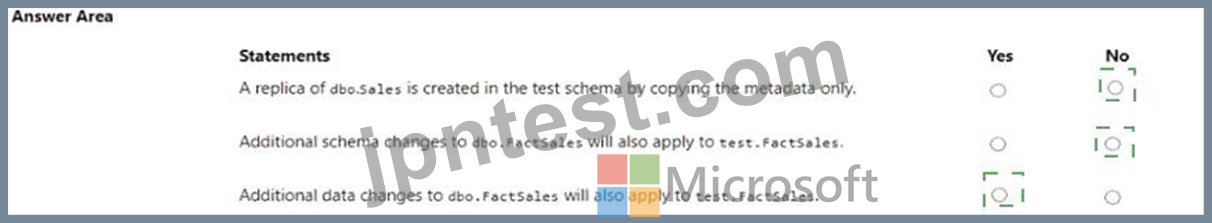
Explanation:
* A replica of dbo.Sales is created in the test schema by copying the metadata only. - Yes
* Additional schema changes to dbo.FactSales will also apply to test.FactSales. - No
* Additional data changes to dbo.FactSales will also apply to test.FactSales. - No The CREATE TABLE AS CLONE statement creates a copy of an existing table, including its data and any associated data structures, like indexes. Therefore, the statement does not merely copy metadata; it also copies the data. However, subsequent schema changes to the original table do not automatically propagate to the cloned table. Any data changes in the original table after the clone operation will not be reflected in the clone unless explicitly updated.
References =
* CREATE TABLE AS SELECT (CTAS) in SQL Data Warehouse
質問 # 38
次の図に示す Python コードと出力を含む Fabric ノートブックがあります。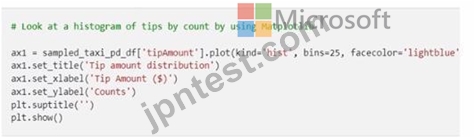
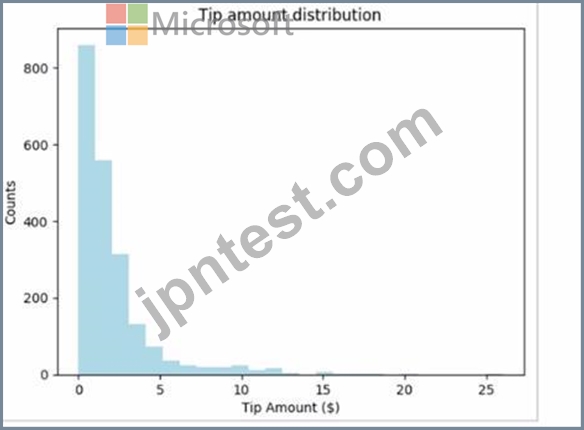
どのタイプの分析を実行していますか?
- A. 診断
- B. 予測
- C. 規範的
- D. 説明的なもの
正解:D
解説:
The Python code and output shown in the exhibit display a histogram, which is a representation of the distribution of data. This kind of analysis is descriptive analytics, which is used to describe or summarize the features of a dataset. Descriptive analytics answers the question of "what has happened" by providing insight into past data through tools such as mean, median, mode, standard deviation, and graphical representations like histograms.
References: Descriptive analytics and the use of histograms as a way to visualize data distribution are basic concepts in data analysis, often covered in introductory analytics and Python programming resources.
質問 # 39
Lakehouse1 という名前のレイクハウスを含む Fabric テナントがあります。 Lakehouse1 には、CSV ファイルを含む Subfolder1 という名前のサブフォルダーが含まれています。 CSV ファイルを、V-Order 最適化が有効になっているデルタ形式に変換する必要があります。 Lakehouse エクスプローラーから何をすればよいですか?
- A. 最適化機能を使用します。
- B. テーブルへのロード機能を使用します。
- C. [テーブル] セクションに新しいショートカットを作成します。
- D. [ファイル] セクションに新しいショートカットを作成します。
正解:B
解説:
To convert CSV files into the delta format with Z-Order optimization enabled, you should use the Optimize feature (D) from Lakehouse Explorer. This will allow you to optimize the file organization for the most efficient querying. References = The process for converting and optimizing file formats within a lakehouse is discussed in the lakehouse management documentation.
質問 # 40
DirectQuery セマンティック モデルを含む Fabric ワークスペースがあります。このモデルは、5 億行を持つデータ ソースをクエリします。
このモデルを使用する Report1 という名前の Microsoft Power Bl レポートがあります。報告!複数のページにビジュアルが含まれています。
すべてのページのビジュアルに対するクエリの実行時間を短縮する必要があります。
使える2つの機能とは何ですか?それぞれの正解は完全な解決策を示します。
注: 各正解は 1 ポイントの価値があります。
- A. OneLake 統合
- B. クエリのキャッシュ
- C. ユーザー定義の集計
- D. 自動集計
正解:A、B
解説:
User-defined aggregations (A) and query caching (C) are two features that can help reduce query execution time. User-defined aggregations allow precalculation of large datasets, and query caching stores the results of queries temporarily to speed up future queries. Reference = Microsoft Power BI documentation on performance optimization offers in-depth knowledge on these features.
質問 # 41
倉庫を含む Fabric テナントがあります。ウェアハウスは行レベルのセキュリティ (RLS) を使用します。ウェアハウスのデルタ テーブルと RLS を使用する Direct Lake セマンティック モデルを作成します。ユーザーがモデルから構築されたレポートを操作するとき、DAX クエリではどのモードが使用されますか?
- A. デュアル
- B. インポート
- C. DirectQuery
- D. ダイレクトレイク
正解:C
解説:
When users interact with a report built from a Direct Lake semantic model that uses row-level security (RLS), the DAX queries will operate in DirectQuery mode (A). This is because the model directly queries the underlying data source without importing data into Power BI. Reference = The Power BI documentation on DirectQuery provides detailed explanations of how RLS and DAX queries function in this mode.
質問 # 42
Woritspace1 と Workspace2 という 2 つのワークスペースを含む Fabric テナントがあります。Workspace1 には Lakehouse1 というレイクハウスが含まれています。Workspace2 には Lakehouse2 というレイクハウスが含まれています。Lakehouse! には dbo.Sales というテーブルが含まれています。Lakehouse2 には dbo.Customers というテーブルが含まれています。
テーブルの追加コピーを作成せずに、同じ SQL クエリで dbo.Sales と dbo.Customers の両方を参照するクエリを記述できることを確認する必要があります。
何を使うべきでしょうか?
- A. ビュー
- B. ショートカット
- C. データフロー
- D. 管理対象テーブル
正解:A
質問 # 43
ファブリック テナントがあります。
Spark DataFrame を使用して Microsoft Power Bl ビジュアルを生成する Fabric ノートブックを作成する予定です。
次のコードを実行します。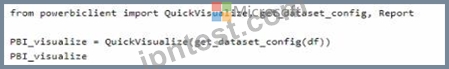
次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。 注: 正しく選択するたびに 1 ポイントの価値があります。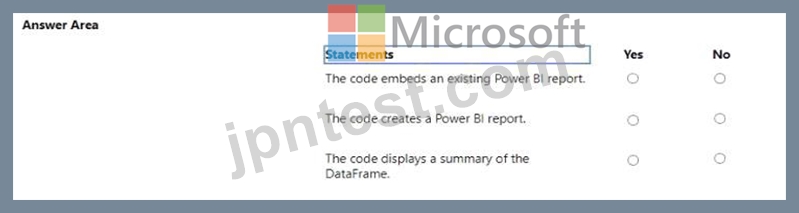
正解:
解説: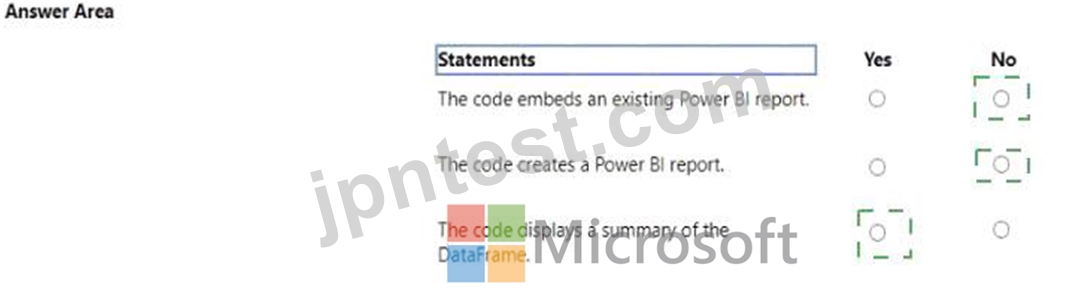
Explanation:
* The code embeds an existing Power BI report. - No
* The code creates a Power BI report. - Yes
* The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report. Instead, it's likely part of a data processing step that summarizes data.
References =
* Introduction to DataFrames - Spark SQL
* Power BI and Azure Databricks
質問 # 44
Microsoft タワー BL Premium 容量を使用するファブリック テナントがあります。セマンティック モデルのスケールアウトを有効にする必要があります。まず何をすべきでしょうか?
- A. セマンティック モデル レベルで、大規模データセットのストレージ形式をオフに設定します。
- B. テナント レベルで、[メトリックの作成と使用] を [有効] に設定します。
- C. テナント レベルで、Data Activator を有効に設定します。
- D. セマンティック モデル レベルで、大規模データセットのストレージ形式をオンに設定します。
正解:D
解説:
To enable scale-out for a semantic model, you should first set Large dataset storage format to On (C) at the semantic model level. This configuration is necessary to handle larger datasets effectively in a scaled-out environment. References = Guidance on configuring large dataset storage formats for scale-out is available in the Power BI documentation.
質問 # 45
......
Microsoft DP-600日本語事前に試験練習テストJPNTest: :https://www.jpntest.com/shiken/DP-600J-mondaishu