

ベスト良質なAdobe AD0-E600試験問題JPNTestリアル練習試験 [2023]
重要な試験問題でAdobe Experience Platform Technical Foundations一発合格
Adobe AD0-E600 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
質問 28
A marketer recently set up an Amazon S3 cloud storage destination. The last successful flow for the destination exported 12 million records. in the Amazon S3 bucket, how will the export be presented to the marketer?
- A. 3 CSV files in the format of: filename.csv {containing 5 million records) filename_2.c$v (containing 5 million records) ftlename_3.csv (containing 2 million records)
- B. 3 JSON files in the format of: filenamejson (containing 5 million records) filename_2json (containing 5 million records) filename.3json (containing 2 million records)
- C. 2 CSV files in the format of filename.csv (containing 6 million records) filename_2.csv (containing 6 million records)
- D. 1 CSV file in the format of: filename.csv (containing 12 million records)
正解: C
質問 29
A data engineer is required to partially ingest data via a Source Connector. Which three source connectors are permitted for this task? (Choose three.)
- A. FTP/SFTP
- B. Microsoft Dynamics
- C. Azure Blob Storage
- D. Adobe Analytics
- E. Web SDK
- F. HTTP API
正解: A,C,D
質問 30
A data engineer has a file they must ingest with all string fields. The engineer must keep precision of the data when converting string fields to numeric fields. Which two functions could the the data engineer use when making this conversion? (Choose two.)
- A. To .integer
- B. To.float
- C. To.bigint
- D. To.object
- E. To_decimal
正解: A,C
質問 31
What is model scoring in the Data Science Workspace?
- A. Applying a model to a data set
- B. Engineering features for a model
- C. Building a recipe
- D. Building and evaluating a model
正解: D
質問 32
A data engineer exports segmented Real-time Customer Profile data to a new dataset called "Profile Export".
The data engineer needs to directly download the data from the Profile Export dataset using the Data Access API.
Which file format is supported for this use case?
- A. Parquet
- B. JSON
- C. CSV
- D. Blob
正解: B
質問 33
A data engineer creates a custom identity namespace within AEP. However, this custom Identity namespace is the wrong Identity type. What can the data engineer do to update the identity namespace?
- A. Create a new custom Identity Namespace with the correct Identity type.
- B. Delete the customIdentityNamespace from the AEP User-Interface under Identities.
- C. Edit the Identity Namespace type within the AEP User-Interface under Identities.
- D. Using the Identity Namespace APIs, update the custom Identity type.
正解: C
質問 34
A marketer wants to send profile and attributes information to an RT-CDP Destination.
Which destination option should the marketer choose to send profile and attributes information?
- A. Google Ads
- B. Facebook Pixel extension
- C. Amazon S3 cloud storage destination
- D. Google Display and Video 360
正解: C
質問 35
A marketer wants 10 create a segment that qualities profiles from all datasets that are enabled for profile. The use case for the segment is for activation to advertising destinations.
Based on the options for ID stitching and merge method respectively, which type of merge policy is appropriate for this use case?
- A. ID stitching: None
Merge method: Timestamp ordered - B. ID stitching: Private graph
Merge method: Dataset precedence - C. ID stitching: None
Merge method: Dataset precedence - D. ID stitching: Private graph
Merge method: Timestamp ordered
正解: C
質問 36
A daily scheduled segmentation job has already run and completed. However, the data engineer recently created a new segment.
Segment Name: Profile Qualification
Segment ID: Safe34ae-Sc98-4Sl3-8a1d-67ccaaS4bc87
The data engineer wants to evaluate this segment via API.
How should the data engineer proceed?
A)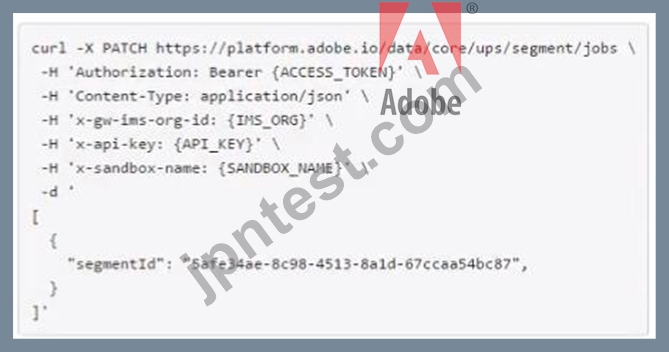
B)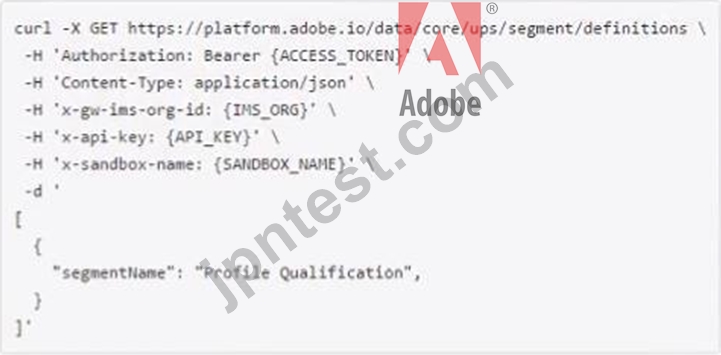
C)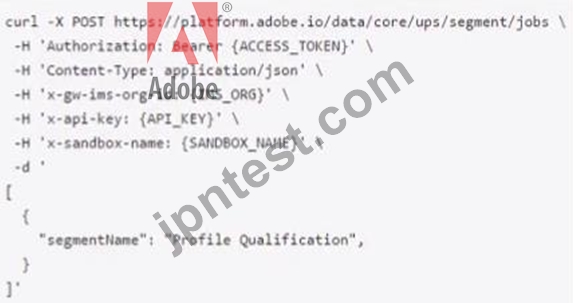
D)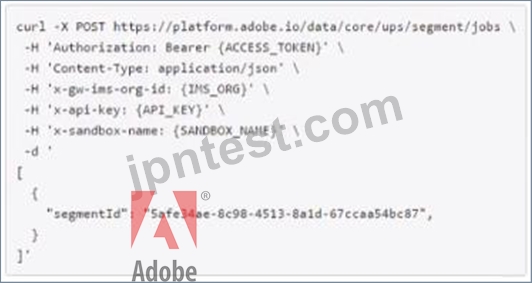
- A. Option C
- B. Option A
- C. Option B
- D. Option D
正解: D
質問 37
After creating the Entity Relationship (Diagram (ERD) of the data sources that will be connected into an AEP implementation for a utility company, the service details (including information such as name, cost type, and category) appear multiple times across different entities (for example, in the transactional events and m the customer profile details).
When designing the XDM data model for that ERD, the data architect and the business stakeholders validate that the service details information must be included at both levels, record, and time series. The service details will be used multiple times within the same structure.
How should the service details be defined in the AEP data model to make it consistent and re-usable?
- A. Create a XDM Schema
- B. Create a Data Type
- C. Create a XDM Class
- D. Create a Field Group
正解: C
質問 38
A data engineer ingests 1000 records that contain various different identities. Each record has at least the primary identity.
The data engineer verifies that the records have been ingested into Data Lake and profile. When clicking on one of the identity namespaces in the identity tab the data engineer sees 100 records under "Records skipped".
What is the possible cause of the skipped records?
- A. Identity service ignores records with only one identity.
- B. Identity namespace is not compatible with identity graph.
- C. Identity records failed XDM validation upon ingestion.
- D. Dataset and schema are not enabled for identity service.
正解: D
質問 39
A marketer notices that the average number of IDs linked per profile has increased significantly over the past couple weeks. In the Identity graph viewer, the marketer sees that different emails that should belong to different profiles are stitched together.
What should the marketer do next to identify the root cause?
- A. Use the Identity API to list the Identity Mappings for the email
- B. Use the Real-time Profile Ul to retrieve the Identity Map linked to the profile
- C. Use Identity graph viewer to retrieve the list of data sources
- D. Use the Identity API to get the details of the Identity Namespace definition
正解: A
質問 40
Given thefollowing: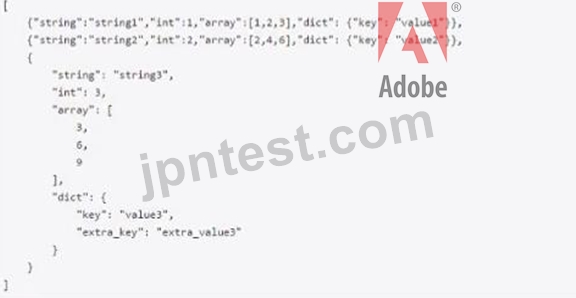
How should a data engineer ingest this data?
- A.
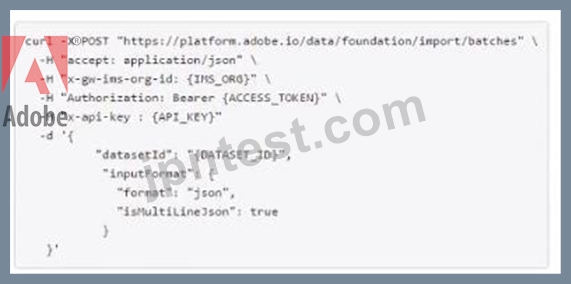
- B. AEP Ul > Locate Dataset > Drag and drop the JSON files
- C.
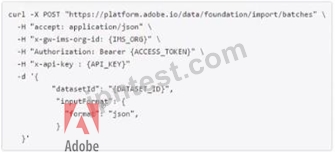
正解: B
質問 41
When sending data through the RESTful API. how can data engineers make sure the payload being sent is formatted property in real time?
- A. All data is ingested and query services reporting identify any records that do not pass custom validation rules.
- B. Leveraging asynchronous validation, data engineers can review error messages for records that fail validation.
- C. Leveraging synchronous validation, data engineers can review error messages for records that fail validation.
- D. As long as the data matches the pre-defined SXM schema, records in the payload pass
正解: D
質問 42
A data engineer it running some tests And tending in event data
How should the data engineer validate that the event is properly attributed to the correct profiler
- A. Use Query service to query events
- B. Use profile lookup to view the events associated to a given profile.
- C. Use the Dataset Preview to look at a few rows and see if data is in profile.
- D. Use the Identity Graph Viewer to view how the identities are mapped.
正解: B
質問 43
Time-series data has been ingested and linked with a Real-time Customer Profile.
A data engineer wants to look up only the most recent time-series event associated with the Luma ID "100".
Which API call will return the desired event object?
A)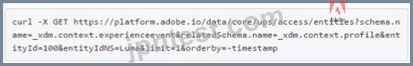
B)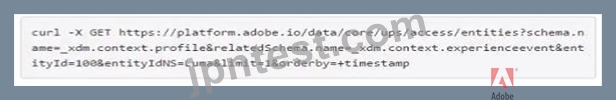
C)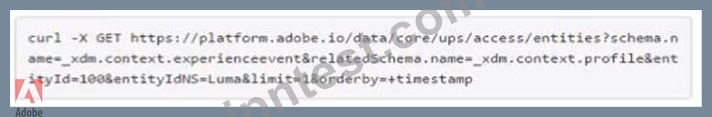
D)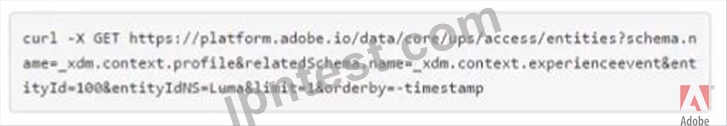
- A. Option C
- B. Option A
- C. Option B
- D. Option D
正解: D
質問 44
A QA engineer needs to determine if the data ingested through three different data sources into three datasets enabled for profile and based in the same XDM Profile schema is processed as expected.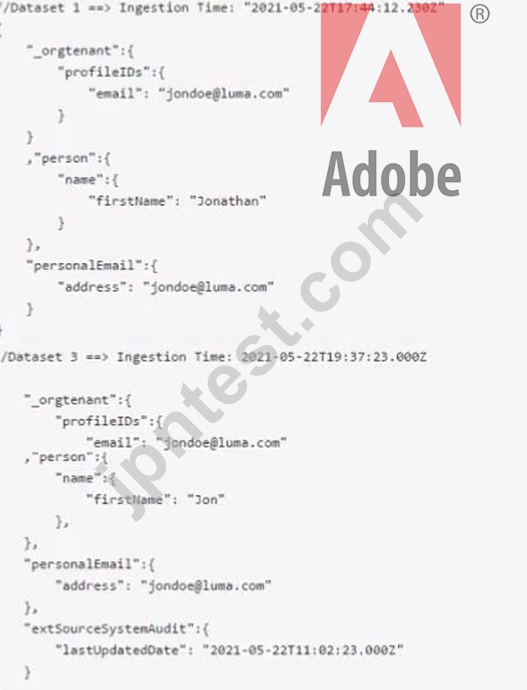
To evaluate the final result, the QA engineer uses the Merge Profile configuration shown;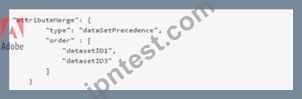
The primary identity used is '.orgtenant.profilelDs.email".
What data should appear m the user profile?
A)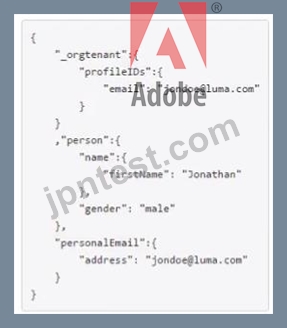
B)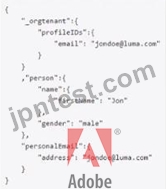
C)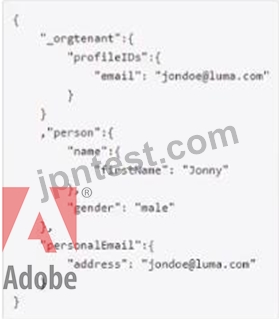
D)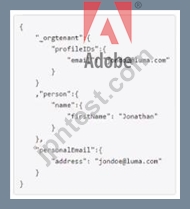
- A. Option C
- B. Option A
- C. Option D
- D. Option B
正解: D
質問 45
A data engineer needs to bong m data via cloud storage sources into the Platform Which two data formats can the data engineer ingest? (Choose two.)
- A. AVRO
- B. JSON
- C. XMKL
- D. CSV
- E. TSV
正解: C,E
質問 46
A B2B business (the client) is migrating its data warehouse (DWH) solution to AEP. Currently, they are using what they call Recipient ID as the main identifier to recognize client employees. That Recipient 10 is generated inside the DWH. That solution will not be available once AEP is live, so the solution architect needs to consider potential alternatives.
After working with the client lead and a data engineer, the solution architect identifies that a combination of Company ID and Hashed Employee Email would be a good replacement for the Recipient ID to make it more unique.
How can the solution architect generate that identity within AEP?
- A. The Company ID (non-people identifier) must be set up as a primary ID. The Hashed Employee Email as a secondary ID and AEP will automatically reconcile them.
- B. The Company ID and Hashed Employee Email must be combined in AEP data prep and passed as a unique primary identity.
- C. The Company ID and Hashed Employee Email must be combined outside of AEP and passed as a unique primary identity.
- D. The Hashed Employee Email must be set up as a primary ID. The Company ID (non-people identifier) as a secondary ID and AEP will automatically reconcile them.
正解: B
質問 47
A data engineer is bringing in audience definitions into Adobe Experience Platform from external sources.
Which standard Experience Data Model (XDM) class should the data engineer use?
- A. Segment Definition
- B. XDM ExperienceEvent
- C. XDM Individual Profile
- D. Profile Definition
正解: B
質問 48
......
AD0-E600試験問題集合格保証:https://www.jpntest.com/shiken/AD0-E600-mondaishu
ベスト良質なAdobe AD0-E600試験問題:https://drive.google.com/open?id=1Du87_YmVeGuGrAa2g6sVTbhO9NQR7SuX